

Models
The AI models a chat can run on, what each can read, and how to pick one.
Every chat runs on one AI model, which reads your messages, uses the tools and writes the replies. You pick it in the model picker and can change it at any time.
Where the model picker is: the chat composer, right of the agent panel button; its menu lists every model you can choose, with a search box. The model's name shows when the composer is wide, and on a phone or in a narrow panel only an icon shows, with the name on hover.
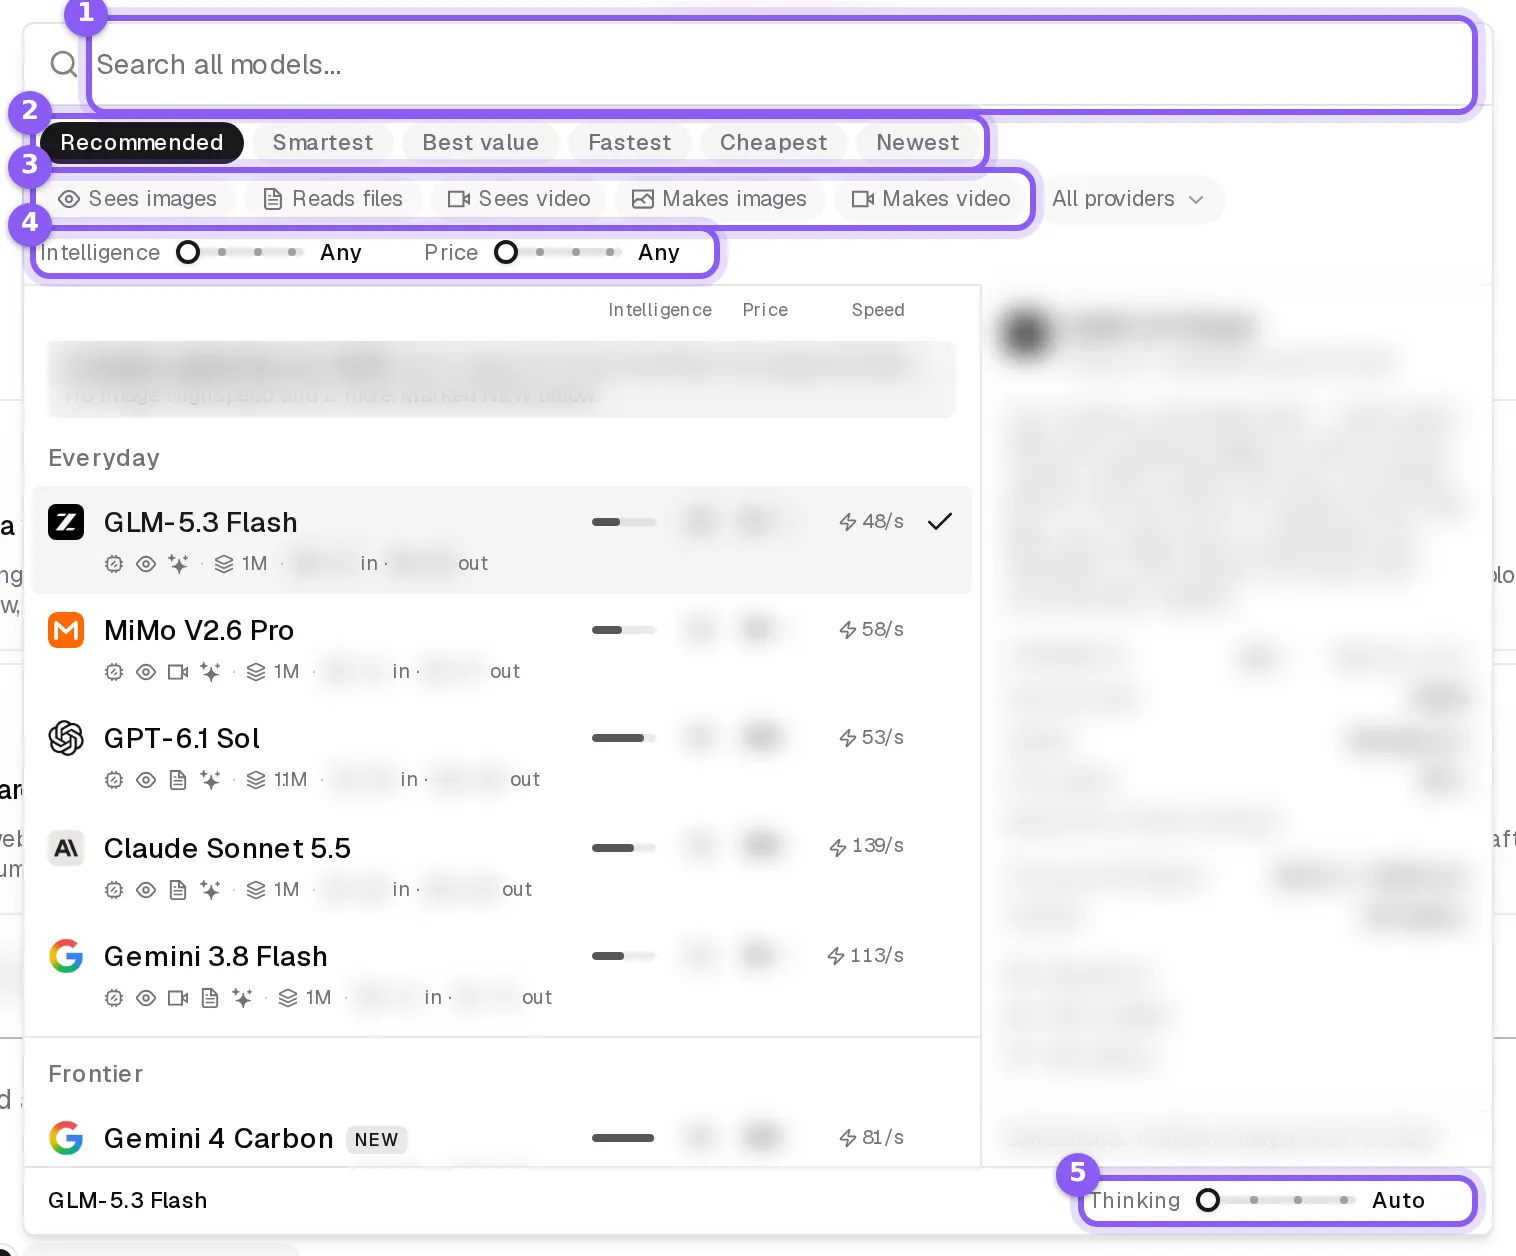
Picking a model
- Open the model picker in the message box.
- Search by name, or narrow the list with the filters: Sees images, Reads files, Sees video, Makes images, Makes video, and the All providers menu for one maker.
- Click a model.
Your pick becomes the model of your new chats. A chat that already has messages keeps the model it was on until you change it in that chat.
The row of sorts at the top changes the order: Recommended, Smartest, Best value, Fastest, Cheapest and Newest. The Intelligence slider hides weaker models and the Price slider hides dearer ones, and Clear filters brings everything back. A model added recently carries a New badge.
A model you cannot afford at the moment is greyed out, and hovering over it says so.
How long it thinks
At the bottom of the picker, the Thinking slider sets how long the model thinks before it answers. Auto leaves it at the model's own default; a higher setting costs more and takes longer. The slider is switched off for a model that does not think.
Recommended models
The picker opens on these sections. They are picked from measured scores and the cost of a typical task, and they change as new models arrive.
Everyday
| Model | Made by | Can read | Context | Price |
|---|---|---|---|---|
| GLM-5.3 Flash (default) | Zhipu AI | images | 1M | $ |
| MiMo V2.6 Pro | Xiaomi | images, video | 1M | $$ |
| GPT-6.1 Sol | OpenAI | images, files | 1.1M | $$$ |
| Claude Sonnet 5.5 | Anthropic | images, files | 1M | $$$ |
| Gemini 3.8 Flash | images, video, files | 1M | $$ |
Frontier
| Model | Made by | Can read | Context | Price |
|---|---|---|---|---|
| Gemini 4 Carbon | images, video, files | 1M | $$$ | |
| GPT-6 Astra | OpenAI | images, files | 1.1M | $$$$ |
| Claude Opus 5.5 | Anthropic | images, files | 1M | $$$$ |
Maximum
| Model | Made by | Can read | Context | Price |
|---|---|---|---|---|
| Claude Fable 5.2 | Anthropic | images, files | 1M | $$$$ |
Budget
| Model | Made by | Can read | Context | Price |
|---|---|---|---|---|
| GPT-6 Luna | OpenAI | images, files | 1.1M | $ |
| DeepSeek V4 Flash 0731 | DeepSeek | text only | 1M | $ |
| MiMo V2.6 Flash | Xiaomi | images, video | 1M | $ |
| Claude Haiku 5.5 | Anthropic | images, files | 1M | $ |
"Can read" is what the model takes besides text, such as an attached image or PDF. "Context" is how much of a conversation it holds at once. "Price" compares the price per word, from $ (cheapest) to $$$$.
Every model
| Model | Made by | Can read | Context | Price |
|---|---|---|---|---|
| Claude Fable 5.1 | Anthropic | images, files | 1M | $$$$ |
| Claude Fable 5.2 | Anthropic | images, files | 1M | $$$$ |
| Claude Haiku 4.5 | Anthropic | images, files | 200K | $$ |
| Claude Haiku 5.5 | Anthropic | images, files | 1M | $ |
| Claude Opus 4.5 | Anthropic | images, files | 200K | $$$$ |
| Claude Opus 4.6 | Anthropic | images, files | 1M | $$$$ |
| Claude Opus 5.5 | Anthropic | images, files | 1M | $$$$ |
| Claude Sonnet 4.5 | Anthropic | images, files | 1M | $$$ |
| Claude Sonnet 4.6 | Anthropic | images, files | 1M | $$$ |
| Claude Sonnet 5 | Anthropic | images, files | 1M | $$$ |
| Claude Sonnet 5.5 | Anthropic | images, files | 1M | $$$ |
| GPT-4.1 Mini | OpenAI | images, files | 1M | $$ |
| GPT-4.1 Nano | OpenAI | images, files | 1M | $ |
| GPT-5 | OpenAI | images, files | 400K | $$$ |
| GPT-5 Mini | OpenAI | images, files | 400K | $$ |
| GPT-5 Nano | OpenAI | images, files | 400K | $ |
| GPT-5 Pro | OpenAI | images, files | 400K | $$$$ |
| GPT-5.1 Thinking | OpenAI | images, files | 400K | $$$ |
| GPT-5.2 | OpenAI | images, files | 400K | $$$ |
| GPT-5.2 Pro | OpenAI | images, files | 400K | $$$$ |
| GPT-5.3 Codex | OpenAI | images, files | 400K | $$$ |
| GPT-5.5 | OpenAI | images, files | 1M | $$$$ |
| GPT-5.5 Pro | OpenAI | images, files | 1M | $$$$ |
| GPT-5.6 Luna | OpenAI | images, files | 1.1M | $ |
| GPT-5.6 Sol | OpenAI | files | 1.1M | $$$$ |
| GPT-5.6 Terra | OpenAI | files | 1.1M | $$$ |
| GPT-6 Astra | OpenAI | images, files | 1.1M | $$$$ |
| GPT-6 Luna | OpenAI | images, files | 1.1M | $ |
| GPT-6 Sol | OpenAI | images, files | 1.1M | $$$ |
| GPT-6.1 Sol | OpenAI | images, files | 1.1M | $$$ |
| GPT-6.1 Terra | OpenAI | images, files | 1.1M | $$ |
| GPT-OSS 120B | OpenAI | text only | 131K | $ |
| GPT-OSS 20B | OpenAI | text only | 131K | $ |
| Gemini 2.5 Flash | images, video, files | 1M | $$ | |
| Gemini 2.5 Pro | images, video, files | 1M | $$$ | |
| Gemini 3 Flash | images, video, files | 1M | $$ | |
| Gemini 3.1 Pro Preview | images, video, files | 1M | $$$ | |
| Gemini 3.5 Flash | images, video, files | 1M | $$$ | |
| Gemini 3.5 Flash Lite | images, video, files | 1M | $$ | |
| Gemini 3.6 Flash | images, video, files | 1M | $$ | |
| Gemini 3.7 Flash | images, video, files | 1M | $$ | |
| Gemini 3.8 Flash | images, video, files | 1M | $$ | |
| Gemini 4 Argon | images, video, files | 1M | $$$ | |
| Gemini 4 Carbon | images, video, files | 1M | $$$ | |
| Grok 4.6 | xAI | images | 500K | $$$ |
| Grok 4.7 | xAI | images | 500K | $$$ |
| Kimi K2.5 | Moonshot | images, video | 256K | $$ |
| Kimi K2.6 | Moonshot | images, video | 262K | $$ |
| Kimi K2.7 Code | Moonshot | images, video | 256K | $$ |
| Kimi K3 | Moonshot | images, video, files | 1M | $$$ |
| Kimi K3.1 Pro | Moonshot | images | 1M | $$$ |
| DeepSeek V3.2 | DeepSeek | text only | 128K | $$ |
| DeepSeek V3.2 Thinking | DeepSeek | text only | 128K | $$ |
| DeepSeek V4 Flash 0731 | DeepSeek | text only | 1M | $ |
| DeepSeek V4 Flash Vision Exp | DeepSeek | images | 1M | $ |
| DeepSeek V4 Pro | DeepSeek | text only | 1M | $$ |
| DeepSeek V4 Pro 0813 | DeepSeek | text only | 1M | $$ |
| DeepSeek V4.1 Flash | DeepSeek | images | 1M | $$ |
| DeepSeek V4.1 Flash 1017 | DeepSeek | images | 1M | $$ |
| GLM 4.5V | Zhipu AI | images | 66K | $$ |
| GLM-4.6 | Zhipu AI | text only | 200K | $$ |
| GLM-4.7 | Zhipu AI | text only | 200K | $$ |
| GLM-5 | Zhipu AI | text only | 203K | $$ |
| GLM-5.1 | Zhipu AI | text only | 203K | $$$ |
| GLM-5.2 | Zhipu AI | text only | 1M | $$$ |
| GLM-5.3 | Zhipu AI | text only | 1M | $$$ |
| GLM-5.3 Flash (default) | Zhipu AI | images | 1M | $ |
| GLM-5.3 FlashX | Zhipu AI | images | 1M | $$ |
| Llama 3.3 70B | Meta | text only | 128K | $$ |
| Muse Ember | Meta | images, files | 1M | $ |
| Muse Spark 1.2 | Meta | images, files | 1M | $$ |
| Muse Spark 1.2 (Contributor) | Meta | images, files | 1M | $ |
| Muse Spark 1.3 | Meta | images, files | 1M | $$ |
| Muse Spark 1.3 (Contributor) | Meta | images, files | 1M | $ |
| Mistral Large 4 | Mistral | images | 1M | $$ |
| Qwen 3.5 Flash | Alibaba | images | 1M | $ |
| Qwen 3.5 Plus | Alibaba | images | 1M | $$ |
| Qwen 3.7 Flash | Alibaba | images | 991K | $ |
| Qwen 3.7 Max | Alibaba | text only | 991K | $$$ |
| Qwen 3.8 Flash | Alibaba | images | 991K | $ |
| Qwen 3.8 Max | Alibaba | images | 262K | $$$ |
| Qwen 3.8 Max 0902 | Alibaba | images | 991K | $$$ |
| Qwen 3.8 Omni Flash | Alibaba | images | 1M | $ |
| Qwen3.8 27B | Alibaba | images, video, files | 262K | $$ |
| MiniMax M2 | Minimax | text only | 205K | $$ |
| MiniMax M3 | Minimax | images, files | 512K | $$ |
| Ling 3.0 Flash | InclusionAI | text only | 256K | $ |
| Mercury 2.5 | Inception | text only | 260K | $ |
| Mercury 3 | Inception | text only | 1M | $ |
| Particle-1 | Particle | images | 1M | $ |
| MiMo V2.6 Flash | Xiaomi | images, video | 1M | $ |
| MiMo V2.6 Pro | Xiaomi | images, video | 1M | $$ |
| Step 5 Preview | StepFun | images | 1M | $$ |
What a model costs
Each step the agent takes is charged at the model's own price, so a long task on an expensive model costs far more than on a cheap one. How a step is charged: Plans and credits.
Pictures and video
Image and video engines are in the picker too, under Makes images and Makes video. Picking one sets the engine the agent draws with; the chat keeps a model that talks. The engines and what each can do: Images and video.
Fine tuning
In a chat with the Tools switch off, a Model Parameters button appears beside the model picker, with settings such as temperature and maximum output.